Software DevelopmentOctober 29, 2026
Shift Left Security: What It Means and Why Teams Shift Smart
What shift left security means, why running every scanner early caused alert fatigue, and how to rank findings by reachability, exploitability, and exposure.
Agix International
Agix International
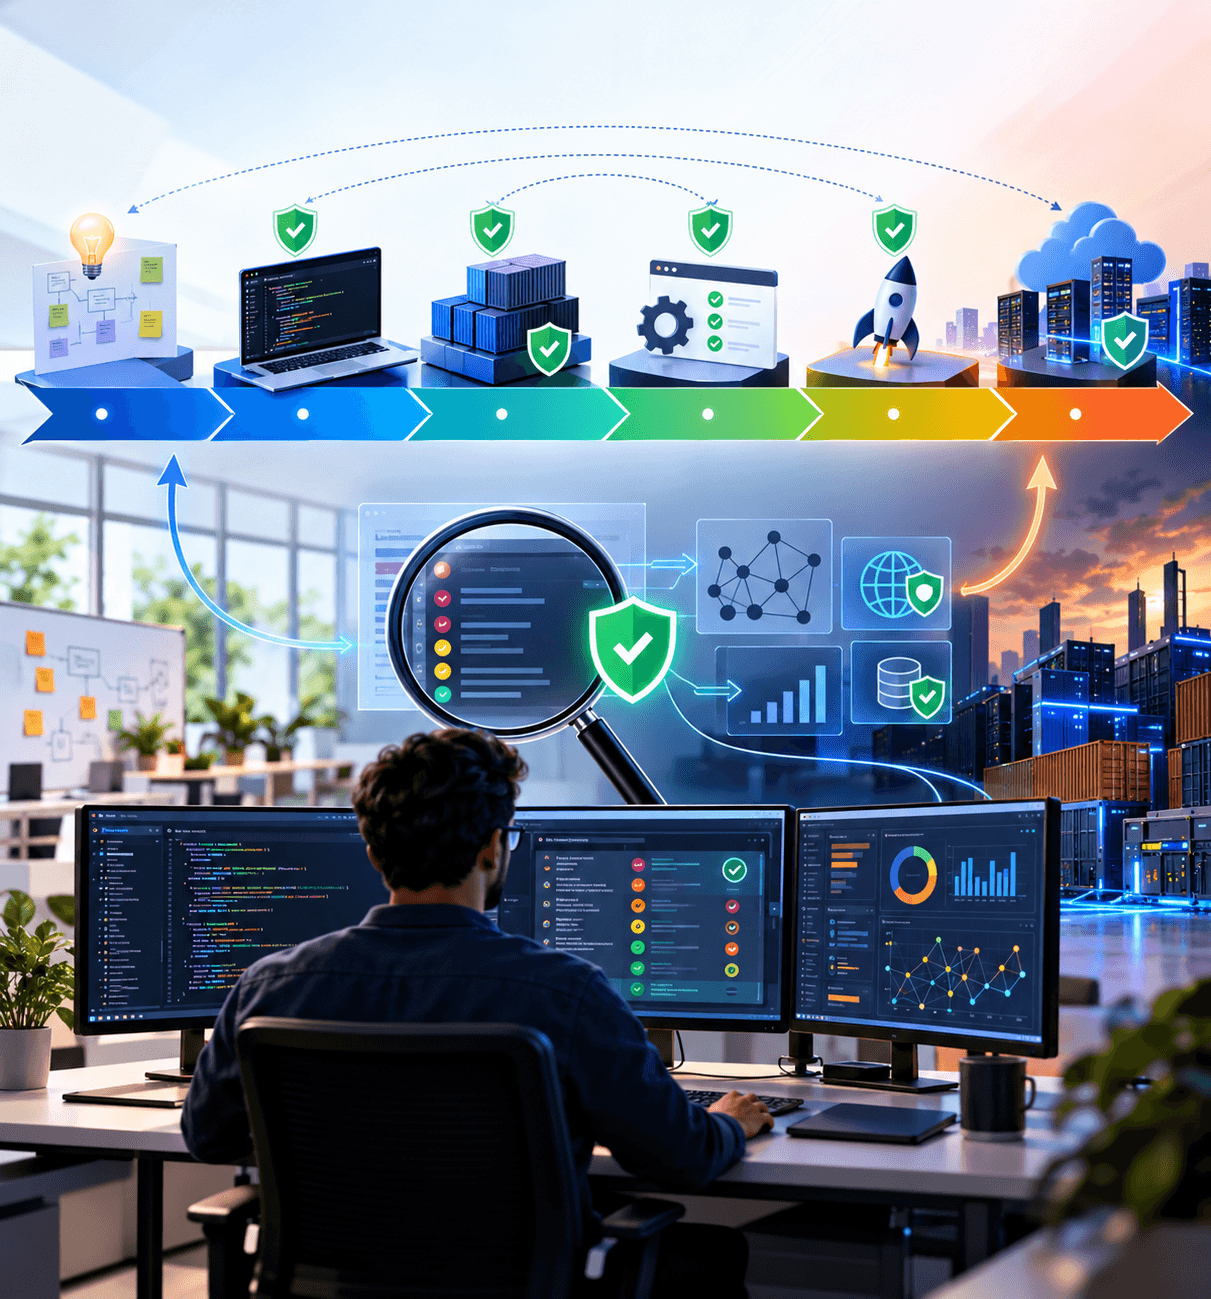
Shift left security means moving security checks earlier in software development, into design, coding, and build, so that problems are found when they are cheapest to fix. "Shift smart" refines the idea: instead of running every check everywhere, teams prioritize findings by whether the flaw is reachable, likely to be exploited, and exposed.
Picture the software life cycle as a line from left to right: plan, code, build, test, release, operate. Traditional security testing happened near the right end, shortly before or after release. "Shift left" was the call to move it toward the start.
The idea was sound, and it is now standard practice. But many teams that applied it literally found that their developers were buried in alerts, many of which did not matter. This article explains what shift left means, what went wrong, and how to do it better. It is part of our DevSecOps guide.
Why Shifting Left Made Sense
A flaw caught while a developer is still writing the code can take minutes to fix. The context is fresh, nothing depends on the code yet, and no customer is exposed. The same flaw found after release needs investigation, a patch, a new deployment, and possibly a disclosure. Finding it late is slower, more expensive, and riskier.
Shifting left also fits continuous delivery. When teams release many times a week, there is no room for a separate security review at the end of each cycle. Security has to run inside the pipeline, on every change.
Typical shift-left practices include:
- Threat modeling during design.
- Secure coding standards and IDE plug-ins that flag risky patterns as code is written.
- Pre-commit hooks that block hardcoded secrets.
- Static analysis (SAST) and software composition analysis (SCA) on every pull request.
- Infrastructure as code scanning before cloud resources are created.
Where Shift Left Went Wrong
Too Many Findings, Too Little Context
Many modern applications depend on hundreds of open-source packages, and scanners report every known vulnerability in each of them. Many of these flaws sit in functions the application never calls. Ranking them by severity score alone produces long lists of "critical" issues that pose little real risk.
Alert Fatigue
When every pull request returns dozens of warnings, developers learn to ignore them. The genuinely dangerous finding gets lost in the noise. Teams start suppressing whole categories of alerts just to keep the pipeline moving.
Developer Friction
Security tools that block builds for low-value reasons create resentment and workarounds. Developers bypass checks, merge with overrides, or push security work to "later," which defeats the purpose.
Ignoring the Right Side
Shifting left is sometimes read as "testing early is enough." It is not. Some risks only appear at runtime: misconfigured cloud services, exposed endpoints, or attacks against code that looked safe in review. A program that only looks left misses them.
What "Shift Smart" Means
Shift smart keeps early checks but adds context so that teams act on what matters. A finding is prioritized by four questions.
| Question | What it tests | Signals and sources |
|---|---|---|
| Is it reachable? | Does our code actually call the vulnerable function? | Reachability analysis in SCA tools, call-graph analysis |
| Is it likely to be exploited? | Is there real-world attack activity or a high chance of it? | The EPSS score, which estimates the probability of exploitation in the next thirty days; the CISA Known Exploited Vulnerabilities catalog |
| Is it exposed? | Can an attacker get to it? | Internet-facing services, authentication requirements, network segmentation |
| Does it matter to the business? | What happens if it is exploited? | Data sensitivity, regulatory scope, service criticality |
A finding that is reachable, exploitable, exposed, and business-critical should stop a release. A finding that fails most of these tests goes into the backlog with a sensible deadline. The severity score still matters, but it is one input, not the decision.
Naive Shift Left vs. Shift Smart
| Practice | Naive shift left | Shift smart |
|---|---|---|
| Which scanners run | All of them, on every commit | The right ones at the right stage |
| How findings are ranked | Severity score only | Severity plus reachability, exploitability, exposure, and business impact |
| What blocks a build | Anything rated high or critical | High-confidence, high-risk findings only |
| Duplicate alerts | Reported by each tool separately | Deduplicated and routed to one owner |
| Production feedback | Rarely used | Runtime findings update rules and tests |
| Success measure | Number of findings | Time to fix what matters, and escape rate |
Shift Everywhere
Shift smart also means looking right. Runtime detection, cloud security posture management, and incident reviews reveal which issues are actually exploited or exposed in production. That information should flow back into threat models, test cases, and pipeline rules. Security becomes a loop rather than a single checkpoint early in the line.
Putting Shift Smart into Practice
- Start in report-only mode. Run your scanners for a few weeks without blocking anything. Measure how many findings appear and how many are genuinely actionable.
- Enable reachability analysis in your dependency scanning, if your tools support it.
- Enrich findings with exploitability data from EPSS and the CISA KEV catalog.
- Deduplicate across tools so one issue produces one ticket, assigned to the team that owns the code.
- Define a short blocking policy. For example, block on exposed secrets and on reachable vulnerabilities that are known to be exploited. Warn on everything else.
- Set remediation targets by risk, not just by severity, and track the age of open findings.
- Feed production back into the pipeline. Every incident or runtime finding should prompt the question: which earlier check should have caught this?
Measuring Whether It Works
Count outcomes, not alerts. Useful measures include the share of findings that developers act on, the time to fix high-risk findings, the number of overrides of blocking checks, and the escape rate: issues found in production that the pipeline should have caught. If developers are acting on most of what they see and the escape rate is falling, the balance is right.
Frequently Asked Questions
What Does Shift Left Mean in Security?
It means doing security work earlier in the software life cycle, during design, coding, and build, instead of only testing before or after release.
Is Shift Left Security Still Relevant?
Yes. Finding flaws early is still cheaper and safer. The change is in how findings are prioritized, so that early checks focus attention instead of overwhelming developers.
What Is Shift Right Security?
Shift right refers to security work in production, such as runtime monitoring, attack detection, and testing live systems. Mature programs combine both directions.
How Do You Reduce Security Alert Fatigue?
Prioritize findings by reachability, exploitability, and exposure; remove duplicates across tools; block only on high-confidence, high-risk issues; and route each finding to a single owner.
Get Your Priorities Right with Agix
Agix International builds DevOps and cybersecurity foundations for growing businesses in India and the GCC. If your pipeline produces more alerts than your team can act on, talk to our engineers. For the wider picture, compare DevOps vs. DevSecOps.